Selected Work - AI

MintCollect - Ask MintCollect, a Claude agent with its own eval

An AI assistant inside a trading-card app with 85K+ accounts: Claude on Amazon Bedrock, working through 32 tools over the company's API with the user's own permissions. It answers from the collection and live market data, finds a card by meaning when the name fails, and turns every change into a proposal the user confirms - and an eval proves it before anyone relies on it.

Role

Founding Engineer / AI

Focus

Agents · Evals · Semantic search

Links

App Store

01The AI problem

A collector asks questions the app answers across five screens: what is my collection worth, is this card worth grading, add it, tell me when the price drops. The job was to give a model those same powers inside the app, without letting it change anything behind the user's back, and to prove it answers correctly before anyone relies on it.

02What I built

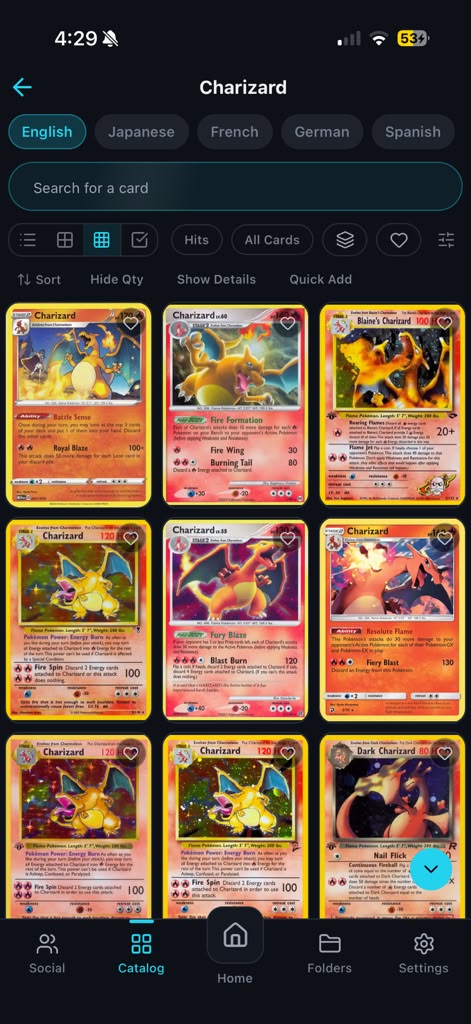
  • Ask MintCollect - a Claude assistant on Amazon Bedrock that answers from the user's collection and live market data, recommends whether a card is worth grading, and adds cards or sets price alerts after a one-tap confirmation.

  • 32 tools over the company's API - the model works through the same REST API the app uses, with the user's own permissions, so it can never see or touch more than the user can.

  • Proposals, not actions - anything that changes data comes back as a proposal the user confirms with one tap. Reads run directly; writes wait for a person.

  • Search by meaning - embeddings stored in pgvector let the assistant find a card from a description when the exact name fails, and it cites the help guides it retrieves.

  • An MCP server - the same tools opened to a user's own Claude client, so the assistant is not locked inside one chat window.

03How a question is answered

Chat in the app

the user's question

MCP client

the user's own Claude

Ask MintCollect

Claude on Amazon Bedrock

32 tools

company API · user's permissions

Embeddings search

pgvector · find by meaning

Help guides

retrieved and cited

Proposals

the user confirms every change

A question reaches Claude with the user's permissions. The model calls tools over the company's API to read the collection and market data, searches by meaning when a name fails, and cites the guides it used. Anything that would change data is returned as a proposal, and nothing is written until the user taps to confirm.

04AI engineering decisions

Every change is a proposal

Problem
An assistant that can add cards and set alerts can do real damage on one wrong guess, and a user cannot audit what a model did behind the scenes.
Approach
I split the tools into reads, which run directly with the user's permissions, and writes, which return a proposal the user confirms with one tap.
Result
The model can act on the account without ever acting behind the user's back.

Pick the model by eval, not by feel

Problem
Defaulting to the largest model is the safe-feeling choice and the expensive one, and nobody knows whether a smaller one would do.
Approach
I ran a 14-question eval across three Claude models and chose the cheapest one that passed.
Result
About $0.0003 per question, against $0.013 on the largest model.

An eval with a judge

Problem
Chat answers are hard to test with exact matches, and a demo that looks right says nothing about the next hundred questions.
Approach
70 questions run three times each, scored by code checks plus a calibrated judge, and a verify-and-repair step for answers that fail a check.
Result
The verify-and-repair step lifted it from 203 to 210 of 210 answers passing.

Search by meaning when the name fails

Problem
Collectors remember a card by what it looks like, not by its exact name, and keyword search returns nothing for a description.
Approach
Embeddings stored in pgvector let the assistant search by meaning, alongside the exact lookups rather than replacing them.
Result
A card found from what the collector means, not only from its exact name.

05How it was built

A Claude agent on the company's own API, measured by its own eval.

Anthropic ClaudeAmazon BedrockTool useMCPpgvector embeddingsEvalsFlask / PythonPostgreSQLAWS

06Outcomes

210 / 210

Eval answers passed (70 questions x 3 runs)

32

Tools over the company's API

~$0.0003

Per question on the model picked by eval